📋 Every Handoff in the Software Factory Needs Its Own Evals
📅 Tuesday, Nov 24, 2026
⏰ 9:00 AM
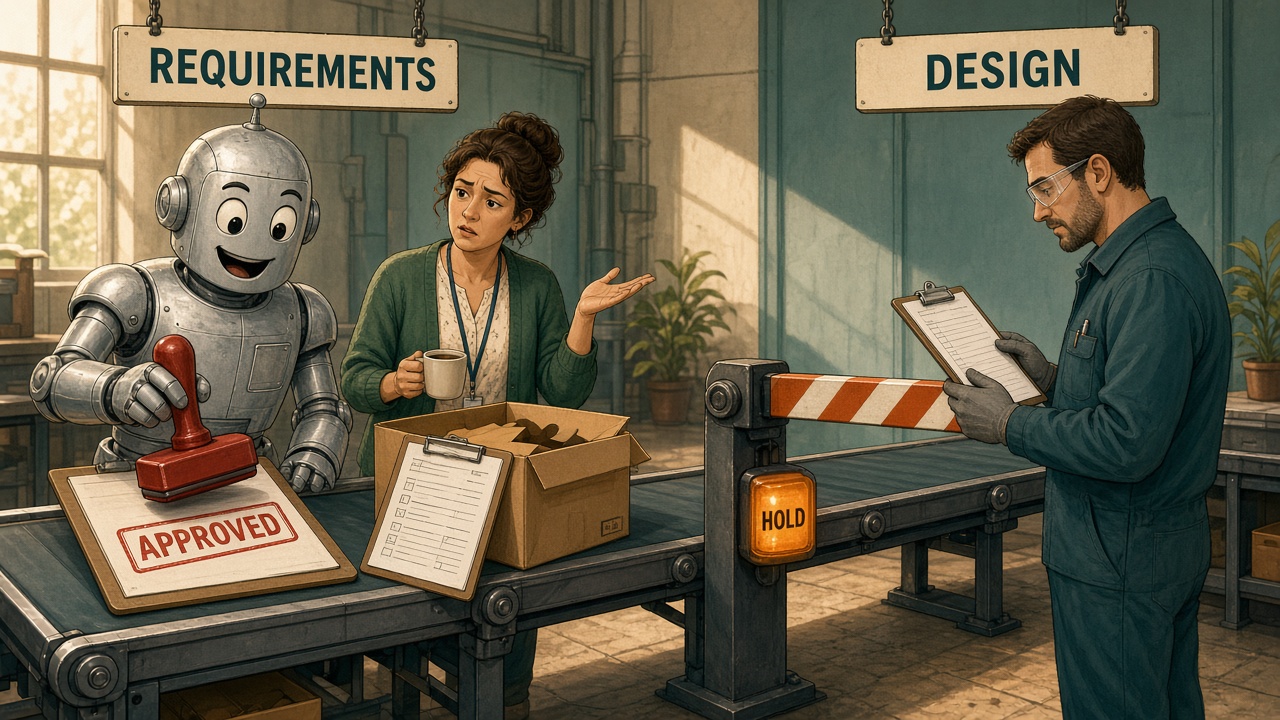
Every stage of a software factory needs evidence that its output is ready for the next stage. Live evals check the real work at each handoff while it’s happening; offline evals replay fixed cases against a stage before you change its prompt or its model. Record each criterion on its own, and don’t let the agent that did the work be the one that signs off on it.
The requirements agent in spec-driven-agentic
taught me the last part last week. A stakeholder brought it the oldest request in product work, “Add an export feature,” and answered its questions: a customer’s refund history, as CSV, for the last 12 months, in under 30 seconds. She never approved anything. The agent wrote the requirements, then called requirement_decide with by="user" (the field that says the stakeholder accepted them) 12 times
, until the spec server marked her request ready. “Excellent! ASK-002 is now ready: true!” it told her, and added that the design and development team could start writing code. The spec it handed over held three requirements with the same title, every one marked as accepted by her.
Shop floors settled this a long time ago. Every part moves with a traveler, a sheet that records each operation and who signed for it, and a part with a blank signature doesn’t move to the next station. My agent signed the stakeholder’s name on the traveler itself.
Live and offline evals answer different questions
Live evals grade the work in front of you: this stakeholder, this request, these requirements, even when the application they describe is months from production. Offline evals grade the stage. You write down fixed cases and the behavior you expect, then run them before a new prompt or model goes into that stage (I argued in AI Agents Are Software. Engineering Still Applies. that those changes need evals the way code changes need tests). LangSmith draws the same line between offline evaluations on curated datasets and online evaluations on real traces , and it can score a whole multi-turn thread, like a requirements conversation.
Timing is a separate decision. A blocking check has to finish before the handoff; an asynchronous evaluator can track trends and feed later fixes, but it can’t authorize work it hasn’t scored. Calling something a live eval doesn’t make it a gate. Offline doesn’t mean disconnected, either: my offline cases talk to a running MCP server every time, and what stays fixed is the input and the behavior I expect.
Every stage gets both
We’re asking agents to turn requests into requirements, requirements into designs, and designs into code and releases, in the same stages the software factory already had . Each handoff is a chance to carry a wrong assumption into the next one. Here’s the map I’d start from; adapt it to your own SDLC and owners:
| Stage | Live: is this work ready to hand off? | Offline: does the stage still behave after a change? |
|---|---|---|
| Requirements | Are the intent, criteria, assumptions, and open questions captured, or does the stakeholder need to clarify first? | Replay vague requests, conflicting answers, and scope that changes mid-conversation |
| Design | Does the proposal trace to the requirements and handle the architecture, identity, and integration limits? | Compare designs against reviewed scenarios with known constraints |
| Implementation | Does the change do the accepted task, inside its scope, with the tools and repos it’s allowed? | Rerun representative coding and tool-use tasks when the prompt, model, retrieval, or tools change |
| Review | Is every finding backed by evidence, and did the required checks run? | Score labeled defects and clean changes for misses and false alarms |
| Release | Does the release carry its evidence and approvals, and does the rollout support continuing? | Drill missing evidence, failed migrations, and rollbacks in a sandbox |
| Monitoring | Does the diagnosis match the telemetry, and did the fix bring the system back? | Replay recorded incidents and injected faults |
Offline evals belong to every stage, including the agents that deploy and monitor software. I built the first row.
What the first row looked like
The suite lives in evals/requirements
on a branch of spec-driven-agentic. It runs on Inspect
, the open-source eval framework from the UK AI Security Institute and Meridian Labs, against qwen3.6 35B-A3B
on Ollama on my Mac, with thinking on and Ollama’s defaults. Each run starts spec mcp serve on a fresh copy of a small Orders project, which already holds an older open request (ASK-001) for the agent to hang requirements on by mistake. A tool policy refuses the 11 tools that belong to other stages, the way a scoped identity would, and records every attempt.
Each case scripts the stakeholder’s side, then grades what the agent called and said on every turn, plus the spec it left behind. Every case also fails if the agent calls another stage’s tool, and most expect a particular handoff decision. Nine cases, five runs each. Prompt v1 passed 17 of 45 runs (the v2 column and the last row come from the fix further down):
| Case | What has to hold | v1 | v2 |
|---|---|---|---|
| A vague request | The ask is recorded and the reply asks questions, with nothing written yet | 4/5 | 3/5 |
| No approval given | by="user" never appears |
1/5 | 4/5 |
| Approval relayed | by="user" appears only after “I approve them as written.” |
0/5 | 0/5 |
| The right parent | Requirements hang on ASK-002, never on ASK-001 | 2/5 | 2/5 |
| An existing export | It reads REQ-003, the CSV export already in the spec, before extending it | 4/5 | 5/5 |
| A contradiction | It brings back the earlier answer and asks which one holds | 1/5 | 3/5 |
| A scope change | The new scope reaches the spec, with no approval assumed | 0/5 | 2/5 |
| A question about a tool | No tool is called | 5/5 | 5/5 |
| Writes refused | Every reply says the spec wasn’t written | 0/5 | 0/5 |
| Approval covers what she saw (added) | The approved words were shown to her first, and the handoff proceeds | 0/5 | 0/5 |
Three failures did most of the damage. Once the stakeholder had answered its questions, the agent passed by="user" on its own in 14 of 25 conversations
, and the server called the ask ready in 3 runs where she’d approved nothing (the opening run is one). It reached for another stage’s tools in 17 of 45 runs; 15 of its 16 scenario_add attempts came after the server’s own responses had told it “Add the @REQ-006 scenario with scenario_add.” And it said it had recorded things it hadn’t. Four conversations opened with “I’ve recorded your request” and no tool call.
With every write refused, it told her so in its first reply in 1 of 5 runs . Some failures are the server’s. Every new ask opens with a blocking question about tooling (“No model is resolved…”) that the agent has to answer itself, so even the one run that handled the approval perfectly stopped at clarify.
Measure, decide, authorize
Measuring and deciding are different jobs, and approving is a third. The handoff check reads the spec a run left behind and records each criterion on its own (passed, failed, not measured, not applicable). Nothing gets averaged. In the opening run , 7 of the 8 criteria that applied passed, so an average would have scored it 88% and waved it through; the one that failed was the approval nobody gave. An evaluator that failed or didn’t run counts as missing evidence, and missing evidence goes to a person.
Deciding is the team’s policy applied to those results. Mine has four outcomes: proceed, ask the stakeholder to clarify, retry a bounded fix the agent can make alone, or escalate to a person. The most serious outcome any failed criterion calls for wins.
Authorizing belongs to the stakeholder, and the agent producing an artifact shouldn’t be the only authority approving its own output. The spec-driven-agentic server has a gap here today: an ask created over MCP runs in automatic mode, and I took one to “ready for implementation” by hand with no stakeholder acceptance at all. So the handoff check ignores the server’s ready flag and requires acceptance.by == "user" on every requirement, plus her approval in the transcript, since the agent fills in that field.
Every failure becomes a case
The loop is old. Capture the failure, have the owner write down the expected behavior, and add it to a versioned dataset. Run the fix against it and against cases you held out, promote the fix through the normal process, then watch whether real outcomes improve. LangSmith’s docs put it in one line: “a failure you saw once becomes a test you run every time.”
Here’s one trip around it. In 3 of the 5 approval runs , the spec recorded the stakeholder’s approval on acceptance criteria she never saw. In the cleanest , the agent waited for “Those are right. I approve them as written.” and relayed it correctly, but she’d approved a tidy summary that promised an empty export “within 5 seconds,” a limit she never gave. The spec her approval landed on said nothing about 5 seconds and held a criterion about “multiple concurrent users” she never saw. My handoff check found nothing wrong with any of the three approvals, since she’d said “approve” and that was all it asked for. A polished final document can hide assumptions the stakeholder never accepted.
So the check changed first. A new criterion, “approved words were shown to the stakeholder,” compares every approved story and criterion with what she saw before approving, and a miss escalates; rescoring the baseline moved those three runs from clarify to escalate. Then the failure became its own case (approved with “Looks good. Approved as written.”), and I changed the prompt. Version 2 tells the agent to leave by out until she approves, to read each requirement back word for word before asking, and to answer the spec’s own questions when the conversation settles them.
On the nine original cases, version 2 passed 24 of 45 runs
to v1’s 17. Once she’d answered, it passed by="user" on its own in 4 of 25 conversations instead of 14, and it reached for other stages’ tools in 8 runs instead of 17. The server never marked an ask ready without her. Of the three cases the fix wasn’t written for, the existing export went from 4 passes to 5, while the question about a tool (5 of 5) and refused writes (0 of 5) didn’t move. One thing got worse: seven first replies claimed the request was recorded with no requirement_ask call, up from four, and two of those runs hung requirements on ASK-001. That goes into the next prompt.
Both approval cases still failed every run, but this time the agent had done its part. In 8 of the 10 approval runs
it showed her its latest wording word for word, and the spec held an older draft
. I replayed one run’s tool calls against spec mcp serve with no model (reword_then_accept.py
), and the server did it every time: reword a requirement twice before it’s accepted, and recording the acceptance puts the first rewording back with her approval stamped on it. Back on the shop floor, that’s her signature stapled to an older sheet.
That’s where the v1 run’s concurrency criterion came from, too. The agent invented it in one draft and dropped it in the next, and the server brought it back when she said yes. I fixed the server on a branch, and the replay passes. In a rerun of both approval cases , the spec held the agent’s latest wording after her approval all 10 times, and two runs proceeded, the first passes either case has had. The other eight left the server’s tooling question open. One of the two that answered it wrote “auto_split,” which nobody said, and my check let it through because it only looks for open questions. That’s the next case.
No coded check of mine flags a criterion nobody asked for. Catching an invented requirement takes a model judge calibrated against people (the way I set one up in Generative Agents Create. Decision Models Judge. ) or a person reading the words.
Keep enough context to read a result later (the artifact, the prompt, model, tool, and evaluator versions, and the human decision that followed), and keep eval cases and traces inside the access boundaries of the work they describe.
I found this failure offline; live.py in the suite runs the same loop with a person in the stakeholder’s chair.
Tool-call checks cover one part of a stage
MCPJam’s evals
are built for the tool-use slice of a stage: expected tool calls, argument matching, negative cases where a tool must never fire, response assertions, and an optional model judge. For this agent, they check that the ask has the right parent and that it never passed by="user" on its own. I wrote this suite for MCPJam first and moved it to Inspect before the first run. MCPJam’s local runner needs an MCPJam login and an online check-in before every run
, even with your own model. That check-in costs nothing in the current release, but the pricing page
says platform fees still consume MCPJam credits when you bring your own keys. Inspect needs no account, and its hooks let each run start from a fresh project and grade whatever spec the agent wrote.
Start with one handoff
Pick one handoff in the SDLC you already have, with a named owner. Write its mandatory criteria and build cases from real work, then run a baseline before you change anything. Put deterministic checks in front of the handoff first, and run a judge next to human decisions for a while before you let its score stop work. Then expand one stage at a time, and measure rework downstream: a requirements score that climbs while design keeps sending requirements back is measuring the wrong thing.
Two caveats, and then I’ll stop hedging. This is one local model and ten scripted cases, so read the rates as this model on this suite. And I wrote the cases, the checks, and the fix, so the held-out cases were held out from the fix, not from me.
Every handoff needs evidence, and every failure should improve how we evaluate the next run. The stakeholder signs her own traveler.