🏛️ Conway's Law Meets the Corpus Effect
📅 Tuesday, Oct 13, 2026
⏰ 4:30 PM
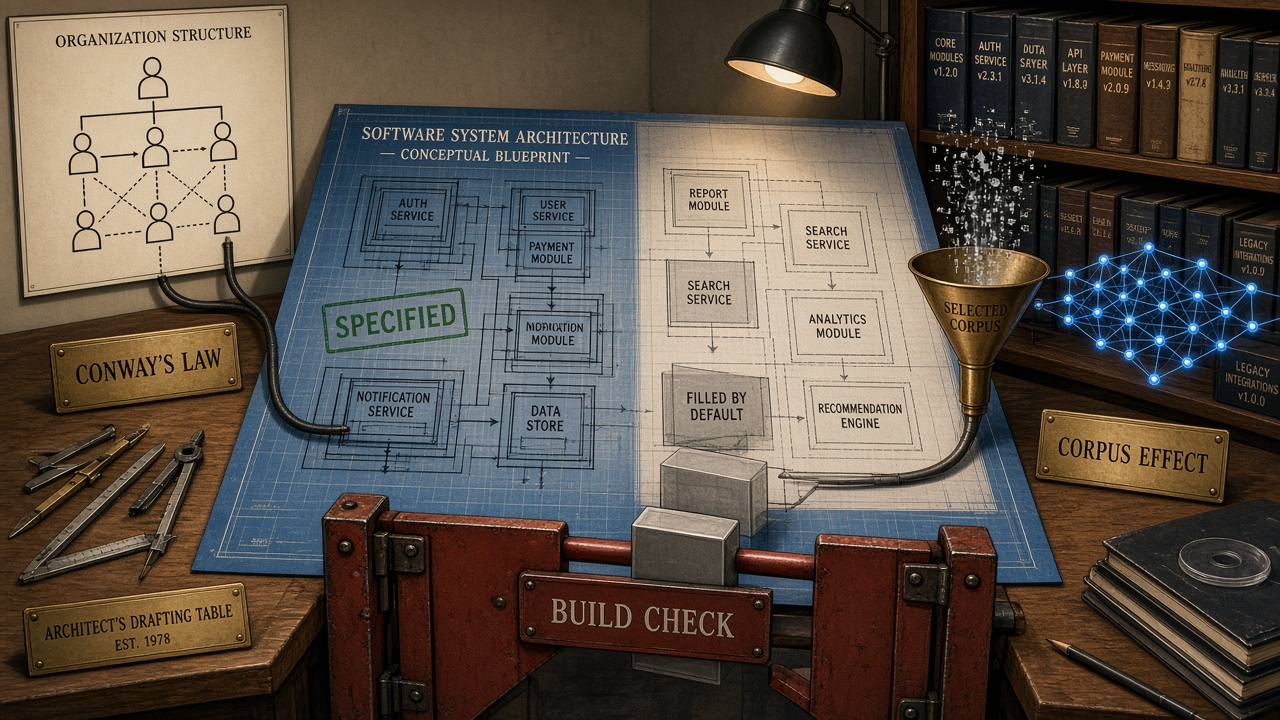
Whose decisions does your software reflect? Yours, wherever you made a decision and enforced it. A model’s, everywhere else.
Generated code settles questions whether or not anyone asked them: the retry policy, the error-handling shape, the module boundary, the shape of the data. Where your organization has an answer and a mechanism that holds the code to it, you get your answer. Where it does not, you get whatever the model learned. And what the model learned shifts under you. In one controlled study, context sitting outside the task specification changed which algorithm it picked by up to 100 percentage points , with every version passing the same tests.
I call that the Corpus Effect: the influence of learned model defaults on software design, especially where organizational intent is unspecified or unenforced. Both of those last words matter, because writing intent down and enforcing it are different jobs.
That is the conclusion. Everything below is where it came from, what the evidence actually supports, and where it stops.
Melvin Conway submitted “How Do Committees Invent?” to the Harvard Business Review in 1967. They rejected it on the grounds that he had not proved his thesis. Datamation published it in April 1968, Fred Brooks cited it in The Mythical Man-Month and called it Conway’s Law, and the name stuck.
His answer was about people and how they were organized. Mine adds a second source, and like his it is unproven, so it is worth saying up front that the rejection was fair.
What Conway actually claimed
The thesis is in the third-to-last paragraph of a 45-paragraph article: “organizations which design systems (in the broad sense used here) are constrained to produce designs which are copies of the communication structures of these organizations.”
The mechanism he gave is narrower and more interesting than the slogan it turned into. Organizing a design team means certain design decisions have already been made, explicitly or otherwise. In his words : “Given any design team organization, there is a class of design alternatives which cannot be effectively pursued by such an organization because the necessary communication paths do not exist. Therefore, there is no such thing as a design group which is both organized and unbiased.”
That is a claim about structure and coordination, not about culture or values.
Unlike most ideas repeated this often, it has been tested. MacCormack, Baldwin, and Rusnak ran a matched-pair study of software products that did the same job, built by tightly coupled commercial firms on one side and loosely coupled open source communities on the other. They measured modularity as the potential for a change in one component to propagate to others. In every pair, the loosely coupled organization’s product was more modular , by up to a factor of six.
The question Conway did not have to ask
Conway assumed people make the design decisions. The communication structure constrains which decisions are reachable; humans still pick from what remains.
That assumption is now partly false. When generation fills in a choice nobody specified, that choice still comes from somewhere, and it is not the communication structure of your teams. It is what the model learned.
Corpus Effect is the name I put on that, and it needs two caveats. First, it is not mine. “Corpus effect” is an established term in NLP evaluation meaning the influence of a corpus’s composition on measured results; Karimi and colleagues used it in 2007 to show that transliteration accuracy could vary by up to 30 percentage points depending on which corpus you ran against. I am borrowing it for architecture, not coining it. Second, it is a hypothesis. Conway was told his thesis was unproven. Mine is considerably less proven than his.
The model did not learn from all the code
The sloppy version of this argument says the model absorbed every line of code ever written and hands it back averaged.
StarCoder2 is the clearest public example because BigCode documented it. The Stack v2 was built on the Software Heritage archive: over three billion files, 658 detected languages. Then came the selection. The technical report describes license filtering, heuristics to eliminate low-quality code, PII redaction, malicious code removal, and honoring opt-outs from developers who asked to be excluded. The surviving training set is 900B+ unique tokens, and the 3B and 7B models were trained on a 17-language subset of it rather than the 600-plus languages behind the 15B model.
Every one of those is a decision made by people. I made the adjacent argument in Open Source Wrote the Textbooks AI Learned From : the quality of the examples shapes the output. The selection shapes it too.
Post-training narrows the distribution again. Xiao and colleagues showed that the KL-based regularization in standard RLHF carries an algorithmic bias toward majority preferences, which in the extreme becomes preference collapse , where minority preferences are virtually disregarded. An ICLR 2025 paper makes the same case about code: aligned models “approach problems in more uniform ways.”
Then there is the context you supply. Anthropic defines context engineering as “curating and maintaining the optimal set of tokens (information) during LLM inference, including all the other information that may land there outside of the prompts” — system prompt, tools, retrieved files, message history.
So the default that lands in your repository is the product of a selected corpus, a narrowing alignment process, and whatever context you did or did not provide. Only the last one is yours to change.
Three outcomes worth watching
These are hypotheses, not findings.
| Outcome | What it would look like | What the evidence shows today |
|---|---|---|
| Convergence | Different organizations adopt similar model defaults despite different needs | Visible in web design and in implementation detail. An open question for architecture |
| Fragmentation | Separate generation sessions introduce incompatible assumptions into one system | Duplication and reuse metrics moving the wrong way across a large commit dataset |
| Deliberate alignment | Relevant context and enforced constraints steer generation toward intended design | Controlled experiments show defaults shift sharply with context, and that naming the choice works |
Convergence
The strongest evidence is not from enterprise code. Seventy-three graduate students each built a promotional website for a different real business on Lovable, coffee shops, bakeries, gyms, NGOs, IT consultancies, under a grading rubric that explicitly rewarded “creative and original design that avoids generic AI aesthetics.” Eighty-eight percent of the homepages landed in six visual archetypes.
The authors are careful in a way I want to preserve. The count of six comes from one clustering configuration; a sensitivity grid of 60 configurations yields between 3 and 12 archetypes. And they explicitly decline to separate model priors from platform scaffolding, since that requires controlled comparisons they did not run.
Their framing of the mechanism is better than mine: “The most consequential change is who gets to specify: whatever the builder leaves unstated, the production stack settles.”
Closer to engineering, a within-subject study of 20 programmers using GitHub Copilot on Python tasks found that pairwise solution similarity on open-ended system design tasks rose from 0.413 unassisted to 0.505 with the assistant (p = 0.018). The authors conclude that “LLM assistance compresses the solution space most when the task affords the greatest freedom for creative exploration.” Twenty people and four tasks points a direction. It does not establish a rate.
And here is the counterweight I would want anyone quoting me to read. Gordon Burtch studied Kaggle submissions from 2019 to mid-2026 and found substantial syntactic homogenization, with submissions growing more alike in literal syntax and the latent dimensionality of that variation narrowing, alongside little evidence of semantic homogenization . Average semantic distance stayed essentially flat. His conclusion: coding assistants “are certainly standardizing implementation details, yet they have not yet produced evidence of homogenization in the approaches and problem-solving strategies coders employ.”
Convergence on implementation detail is measured. Convergence on architecture is not. He also documents widespread convergence on the random seed value 42, which is funny and is also the mechanism in miniature: a convention that was already in the corpus, reinforced and amplified until it is simply what gets written.
Fragmentation
GitClear analyzed 623 million code changes from 2023 through 2026. Duplicated code blocks climbed from 40.3 to 73.0 per million changed lines , an 81% increase. Moved lines, the fingerprint of refactoring, fell from 21% of changed lines in 2022 to 3.8% year-to-date in 2026. In 2022 developers were roughly twice as likely to refactor as to duplicate; they are now about five times more likely to duplicate.
Read that alongside Sergey Sergeyev, who argues that “AI-generated systems increasingly reflect the context boundaries of the agents involved in their generation” . His piece is about what the agent can see. Mine is about what fills the space inside that boundary. The two compose: the boundary decides what is visible, the corpus decides what gets written when something is not.
One caveat worth stating plainly. GitClear sells tooling for the problem it is measuring, and attributing a commit to a particular model is a heuristic. The direction of those metrics is consistent across four years, which is why I cite them. I would not treat any single figure as precise.
Deliberate alignment
The most useful experiment I found runs 46,535 controlled generations across 11 tasks, 19 cue types, and 15 model configurations. That is where the 100-point swing comes from: incidental context, meaning words and metadata outside the task specification, changed which algorithm family the model chose while every output still passed the same tests. The authors call it an “invisible lottery over performance, security, and maintainability.” The most reliable mitigation they tested was naming the algorithm directly.
That is the whole argument compressed into one result. The default moves with context you did not know you were supplying, so supply it on purpose.
Explicit is not the same as enforced
The second half of that definition is doing as much work as the first.
AGENTS.md is the right instinct and it has real adoption, over 60,000 open source projects, now stewarded under the Linux Foundation. It is also schema-free Markdown with no grammar and no conformance test. Reading it is the agent’s choice, and so is following it.
I made this argument in The Runtime Is the Product : a skill can tell a model “do not refactor on red,” but a runtime can make the invalid transition impossible. An EMNLP 2025 industry paper found that agents struggle to follow complex company policy written as instructions, and that compiling the policy into guard code checked before each action works better.
The architectural version of that guard is a fitness function, which Ford, Parsons, and Kua define as “an objective integrity assessment of some architectural characteristic”
. In Java that is ArchUnit: layeredArchitecture() declares which layer may access which, slices().beFreeOfCycles() rejects dependency cycles, and FreezingArchRule.freeze(rule) records today’s violations so a brownfield codebase fails only on new ones. Python has import-linter, TypeScript has dependency-cruiser. The language does not matter much. What matters is that it runs as a required check and exits non-zero, because a warning everyone has learned to scroll past is enforcement by appearance.
That is what verifiable intent looks like: the model generates whatever the corpus suggests, and the build decides whether it ships.
DORA found the same shape at scale. Ninety percent of their survey respondents use AI at work and the outcomes vary enormously, because the returns come from the organizational system rather than the tools: platform quality, workflow clarity, team alignment.
Conway’s Law still holds. It just has more to decide
The organization still chooses what to specify, what context reaches the model, and what the build refuses. Those are communication decisions, which puts them squarely inside Conway’s mechanism: the class of design alternatives that cannot be effectively pursued, because the necessary communication paths do not exist, now includes a path to a model.
If nobody writes down the retry policy, the model picks one. If nothing fails the build when a domain package imports infrastructure, the import stays. If review ends at “the tests pass,” the corpus made an architectural decision and no one recorded it.
I wrote last week that defaults are what you get when nobody is paying attention . That was about logging. It generalizes.
Conway’s Law was never a promise that organizations get the architecture they want. It was a claim that they get the architecture their communication structure permits. The corpus is now part of that structure. It participates in every decision you leave open, it has read an enormous amount of code you have never seen, and it knows nothing about what your business is for.
Write down what you meant. Then make the build check it.